Repository navigation
fix(voice): show played speech once - #591
Closed
kev (kevchoi) wants to merge 2 commits into
Closed
kev (kevchoi) wants to merge 2 commits into
kev (kevchoi) wants to merge 2 commits into
Conversation


 kev (kevchoi)
changed the title
kev (kevchoi)
added a commit
that referenced
this pull request
Nov 10, 2026
working with @delner on the last mile portion for cascaded/gpt-realtime traces --- LiveKit records generated output in `llm_response` and played speech in `agent_speech`. Represent voice model calls as existing `llm_analysis` work so the thread displays played speech once, while generated messages, tool calls, usage, and timing remain inspectable. No `VoiceTurnRole`, public schema additions, or UI changes. Also preserve unowned `user_speech` intervals as empty standalone turns when the session has no explicit user turns. Keep their IDs and actual intervals without inventing transcripts or replies. Other unowned modeled voice spans are skipped; invalid explicit turn references retain diagnostics. Loaded empty requests remain hidden by the current UI. When no explicit or inherited `turn.id` exists, use the nearest structural `user_turn` or `agent_turn` ancestor in the same session. The search is bounded. Missing ownership is skipped, and invalid explicit IDs remain nonfatal diagnostics; healthy spans continue rendering. No timestamp or text matching. The Realtime fixture covers the attached conversation’s greeting, tool exchange, and closing reply in one fixture and regression test. Expected turns live in JSON; the shared runner checks batching, body/header imports, randomized load order, and coverage. The same fixture is also tested with all `turn.id` fields removed. The orphan-speech and tool fixtures cover separate ownership cases. Implementation reference: [Python SDK #1069](braintrustdata/braintrust-sdk-python#1069). ### Validation - All 105 trajectory tests pass, including the new Realtime regression and existing orphan-speech coverage. Formatting and typed-boundary checks pass. - Fresh Playwright captures compare `03f15aa6` with `13a055ea`: the supplied trace is unchanged; a copy with only `turn.id` removed regains assistant speech and model work. Both runs have no browser page errors. - Independent review found no blockers or dependencies on #591, which is closed. The hosted app still needs its Lingua pin/build updated. Audio-only bubbles and per-turn playback are outside this change. ### Screenshots Latest change, `03f15aa6` → `13a055ea`, with the same app and viewport. Supplied trace with IDs intact: unchanged. 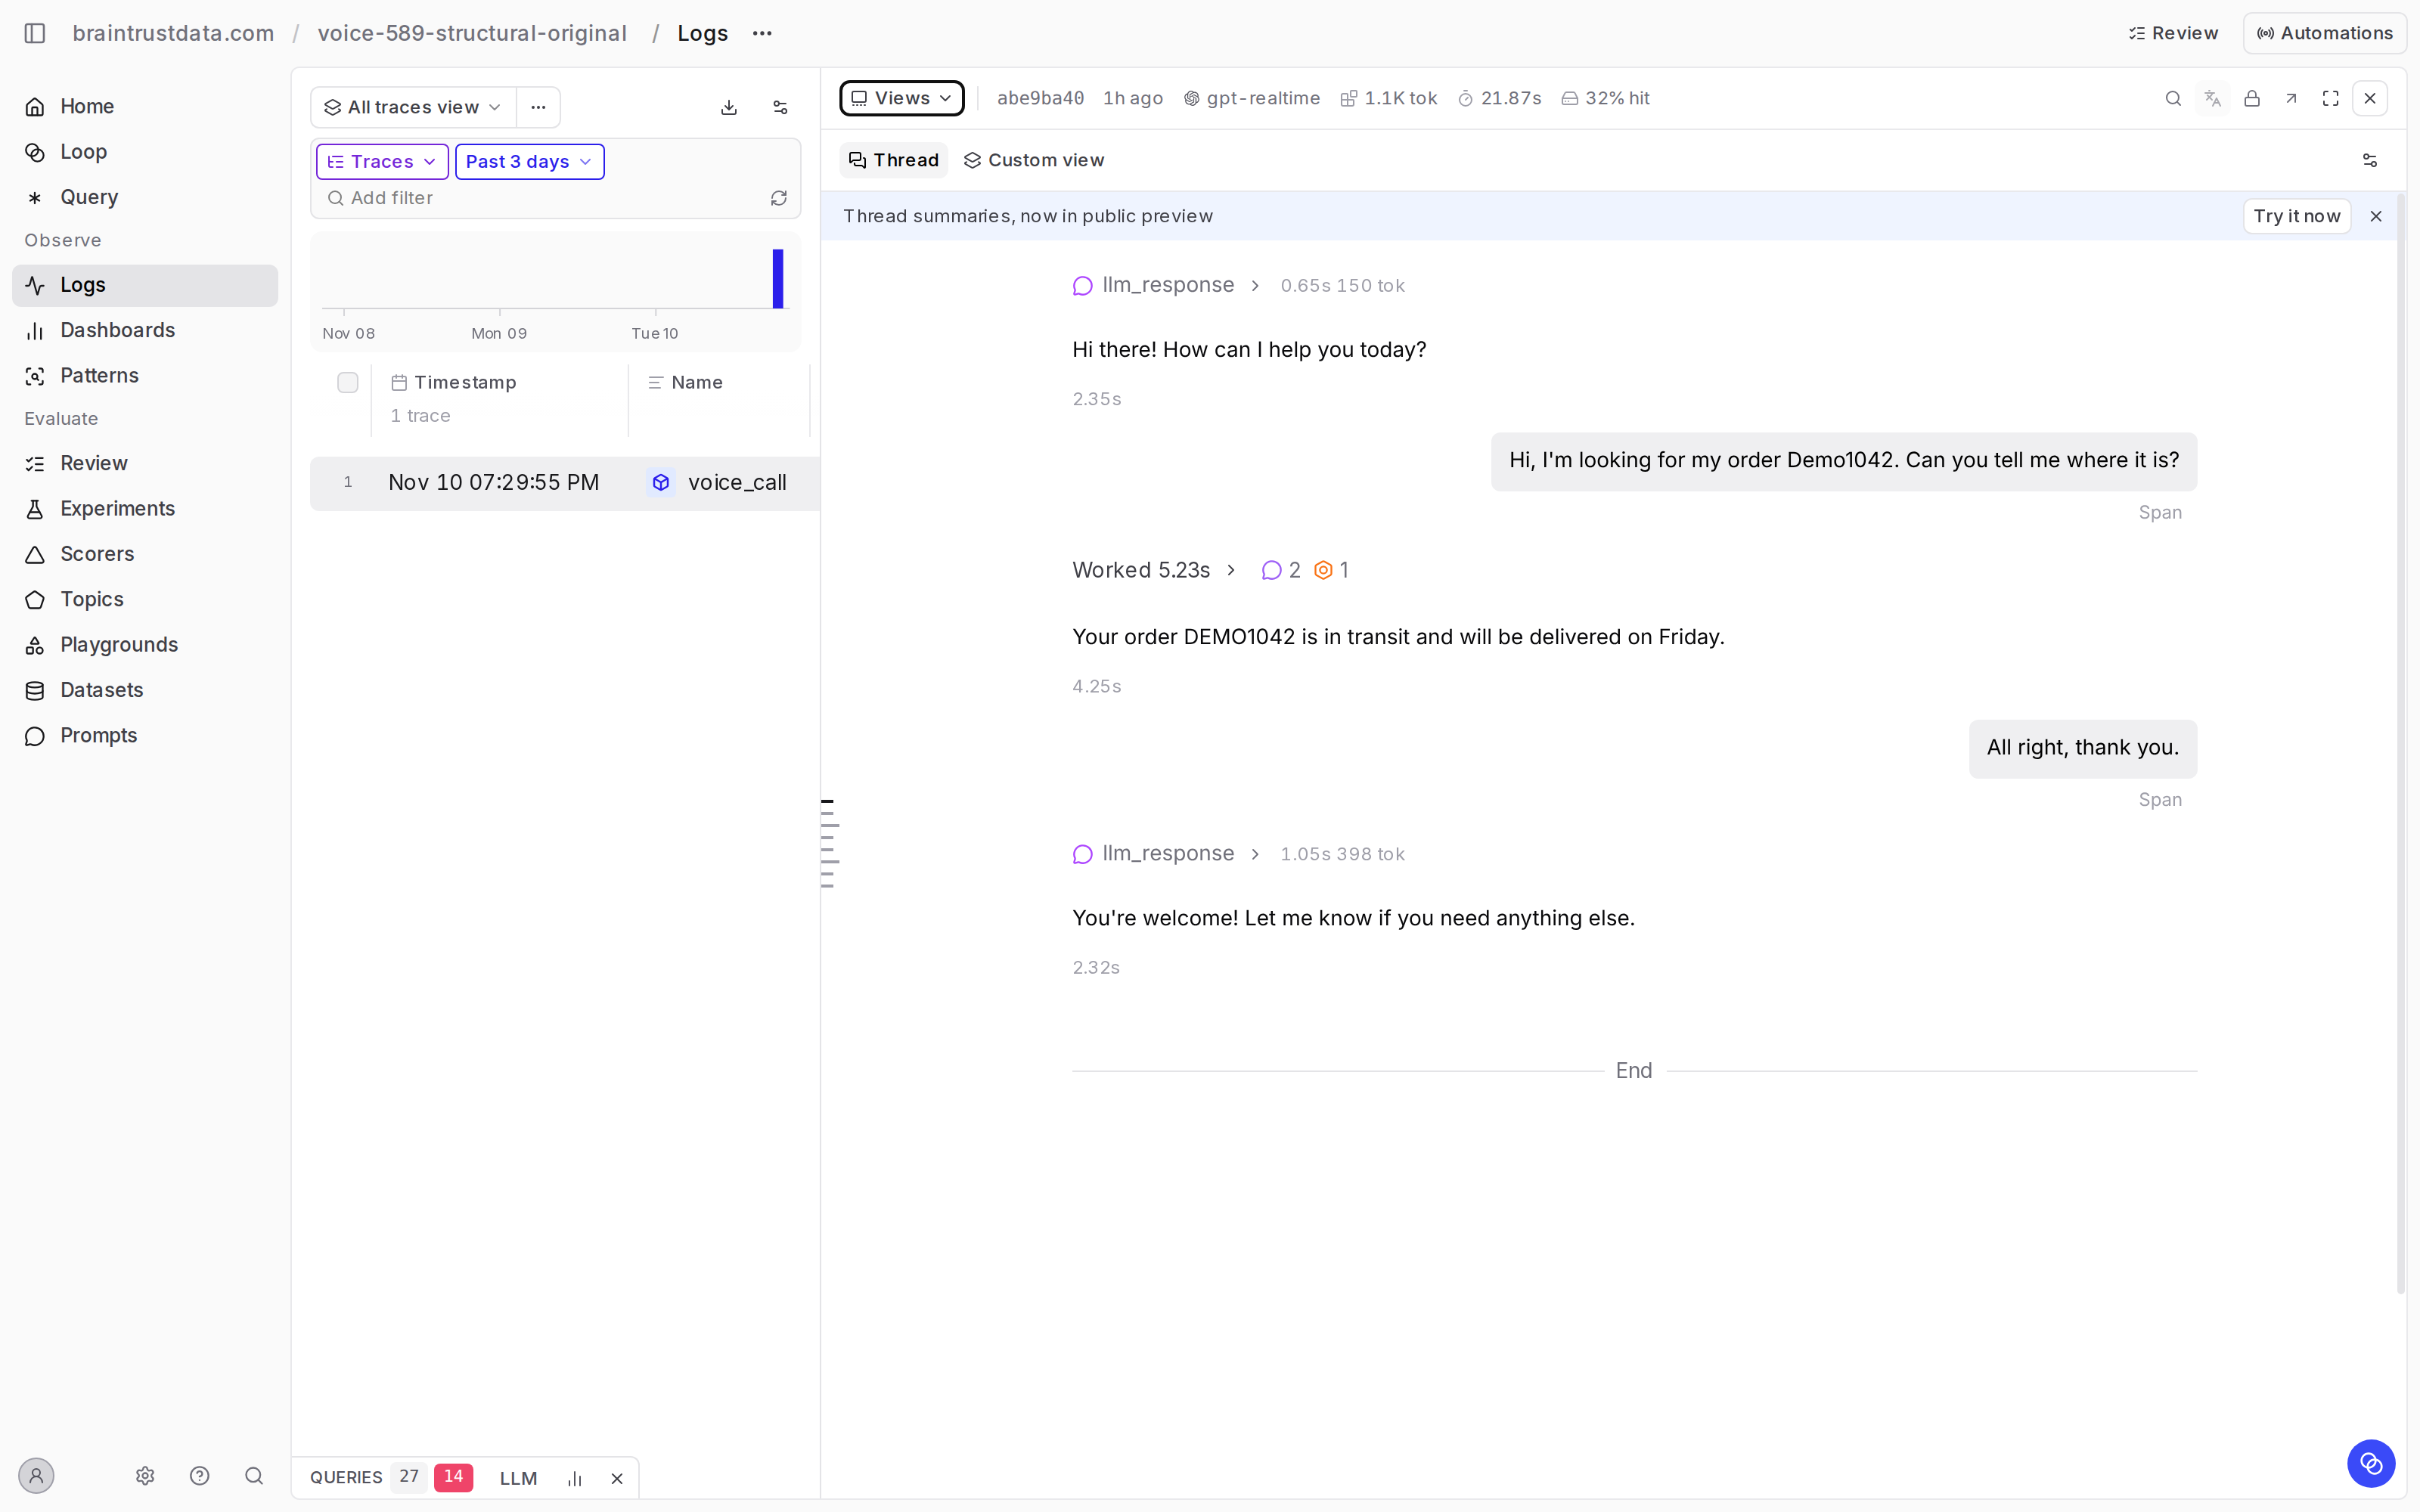 [Open full size](https://api.prod.starfolk.io/api/v1/public/attachments/64D08PUfbIKFheq7HVd0Ud/original-before.png) 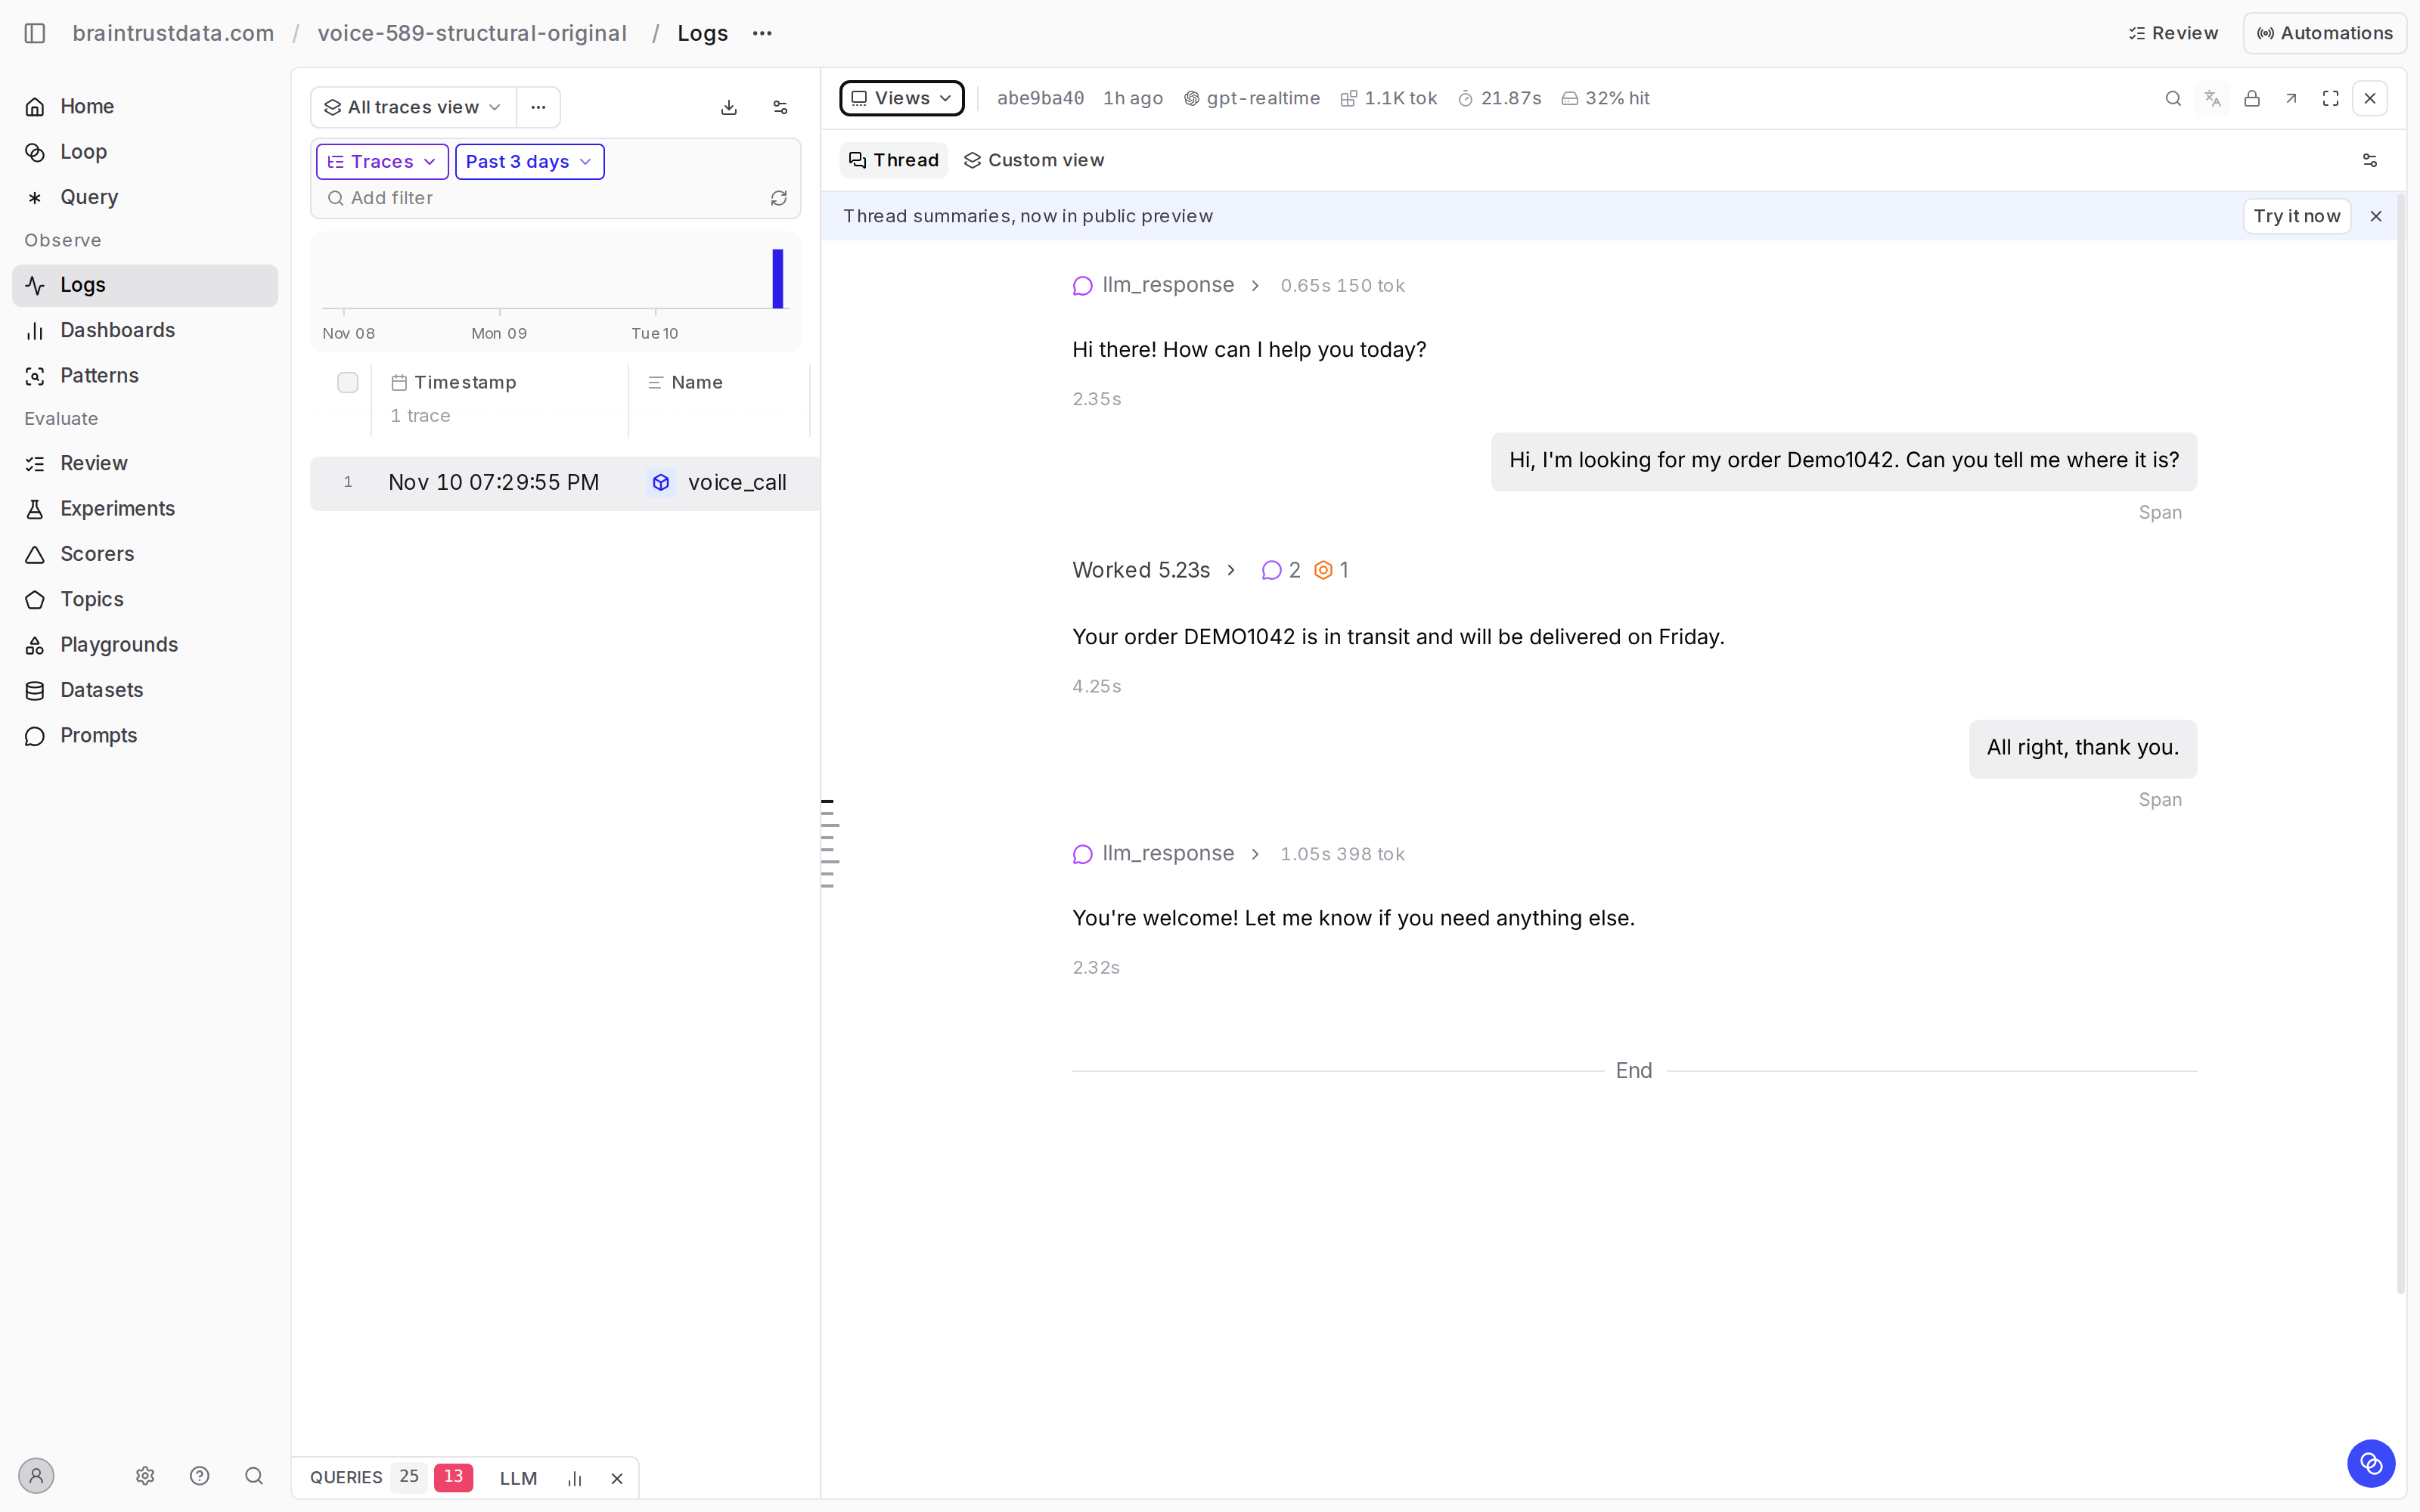 [Open full size](https://api.prod.starfolk.io/api/v1/public/attachments/7OUFEIW0xVMXgQdbGxrq70/original-after.png) Same trace with only `turn.id` removed, before: assistant speech and model work are missing. 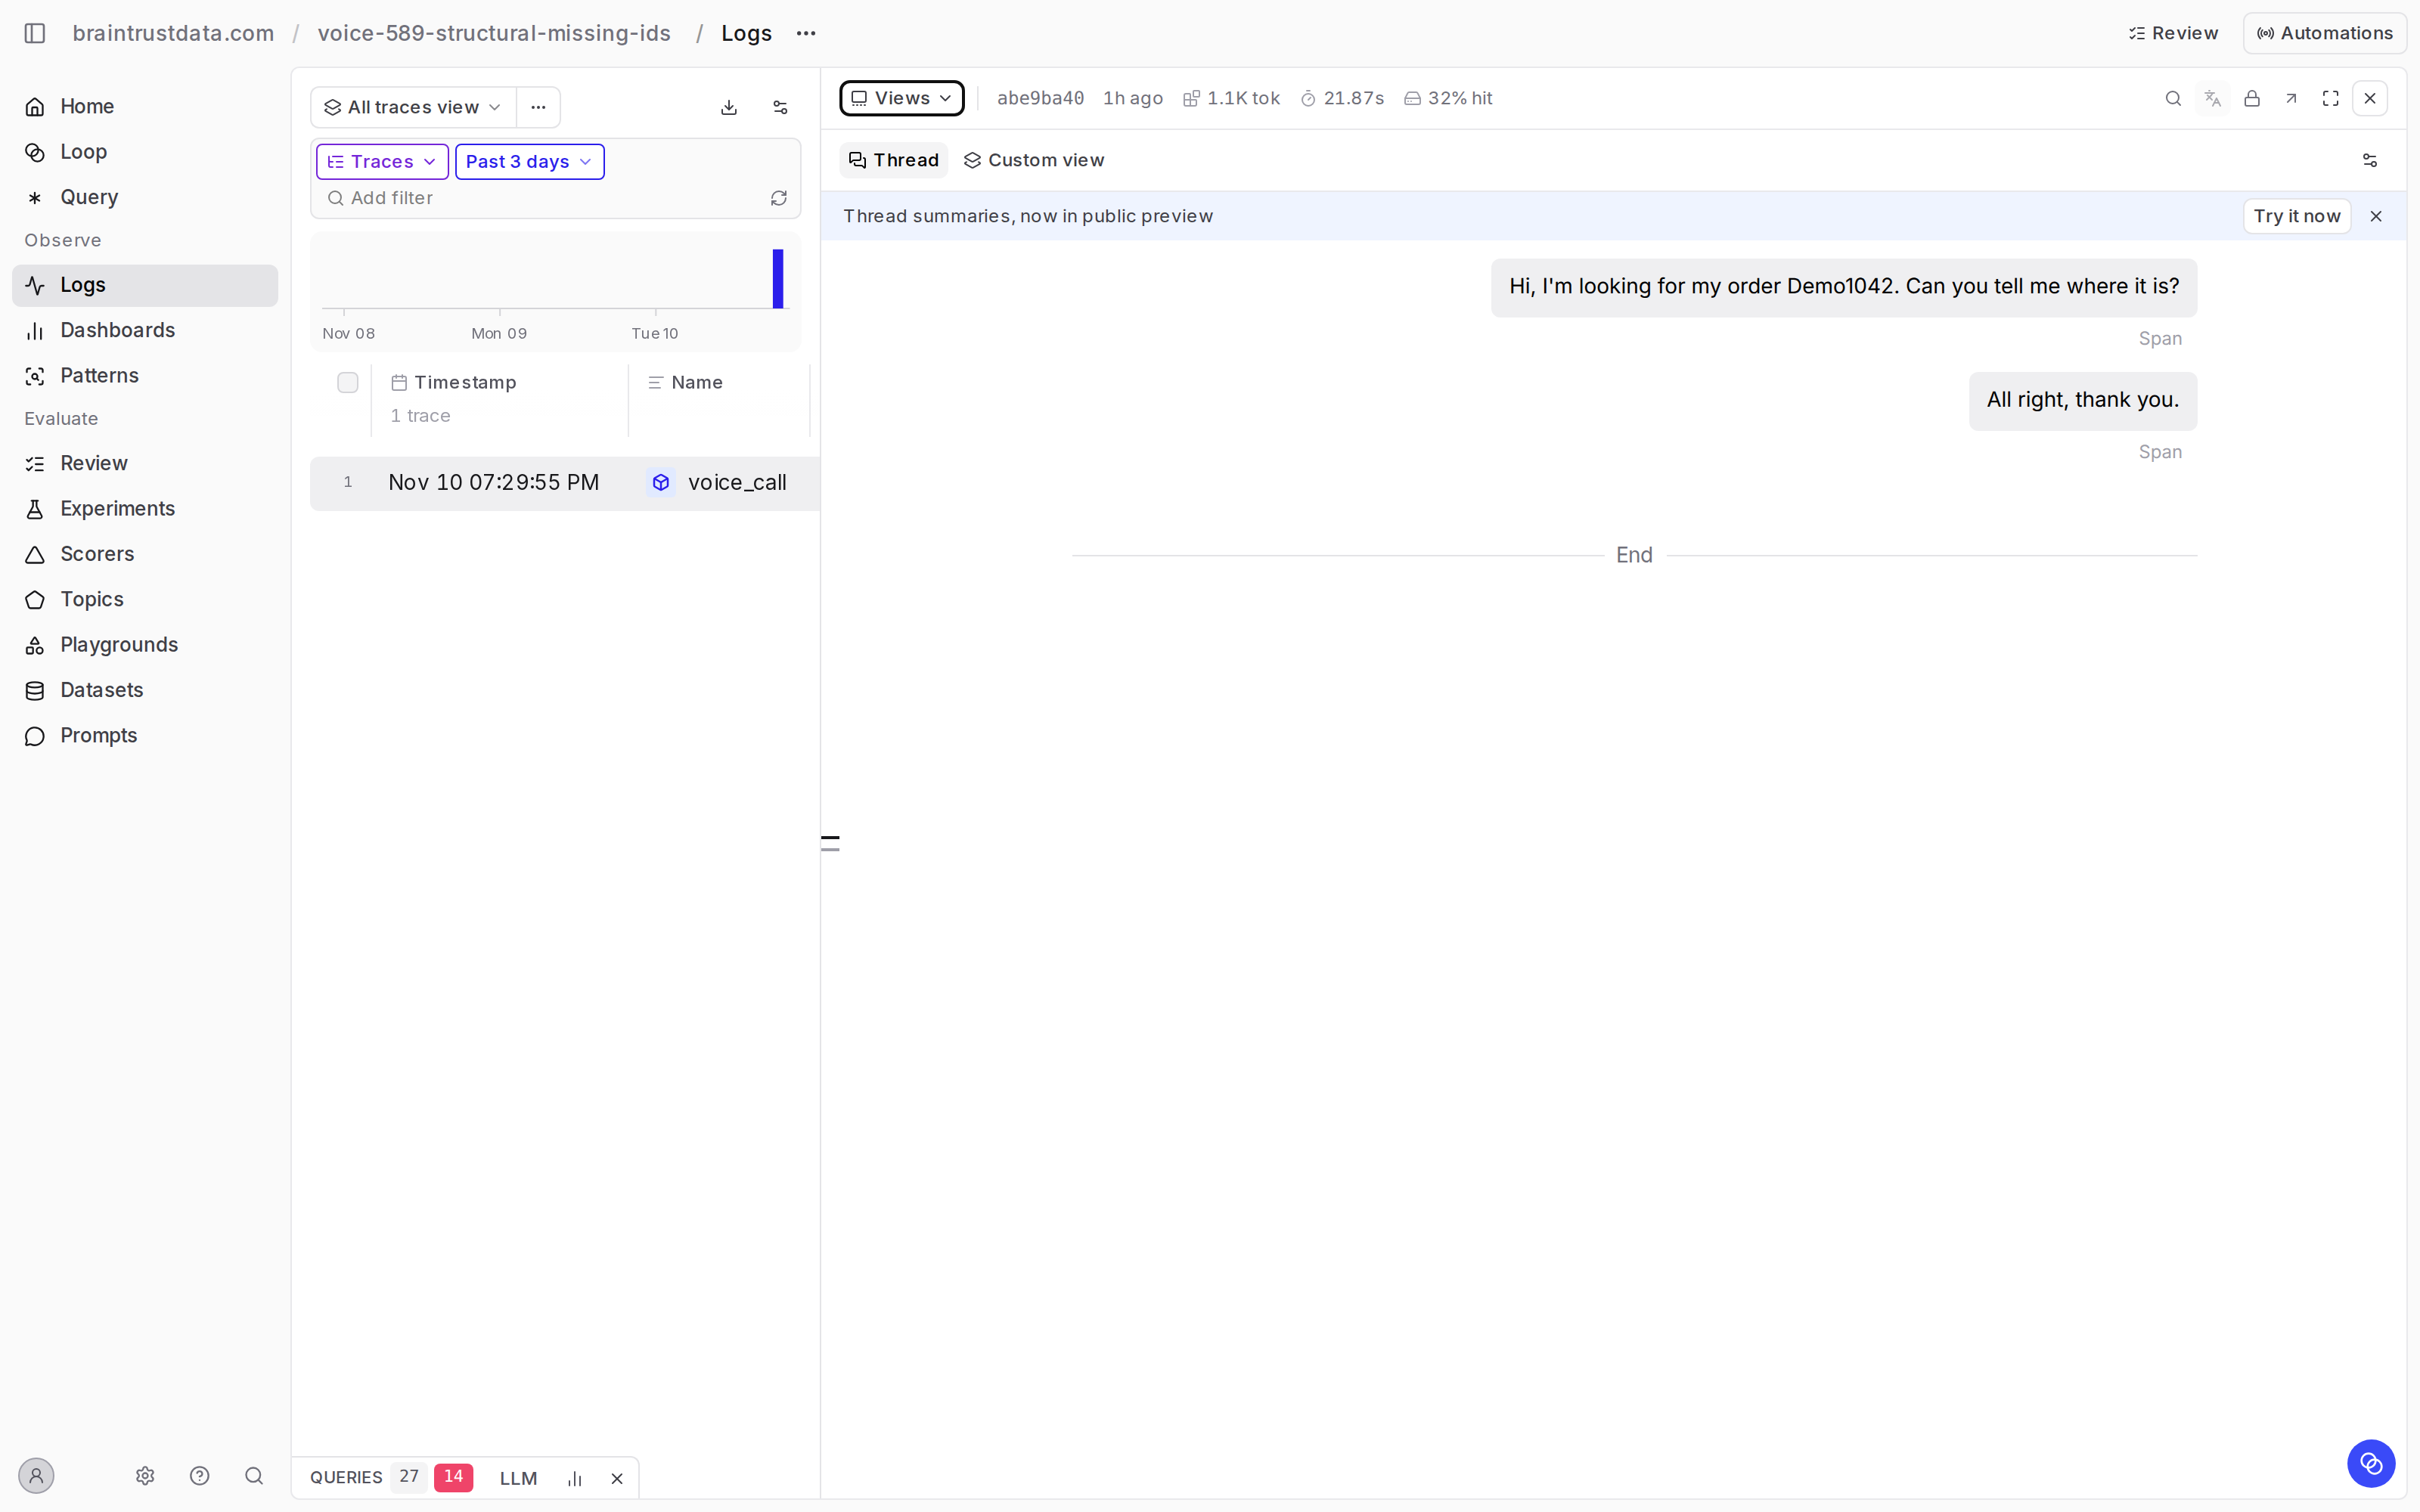 [Open full size](https://api.prod.starfolk.io/api/v1/public/attachments/21fTH7BgVOfxCOhB4L2ceL/missing-turn-ids-before.png) After: structural ownership restores the conversation and model work. 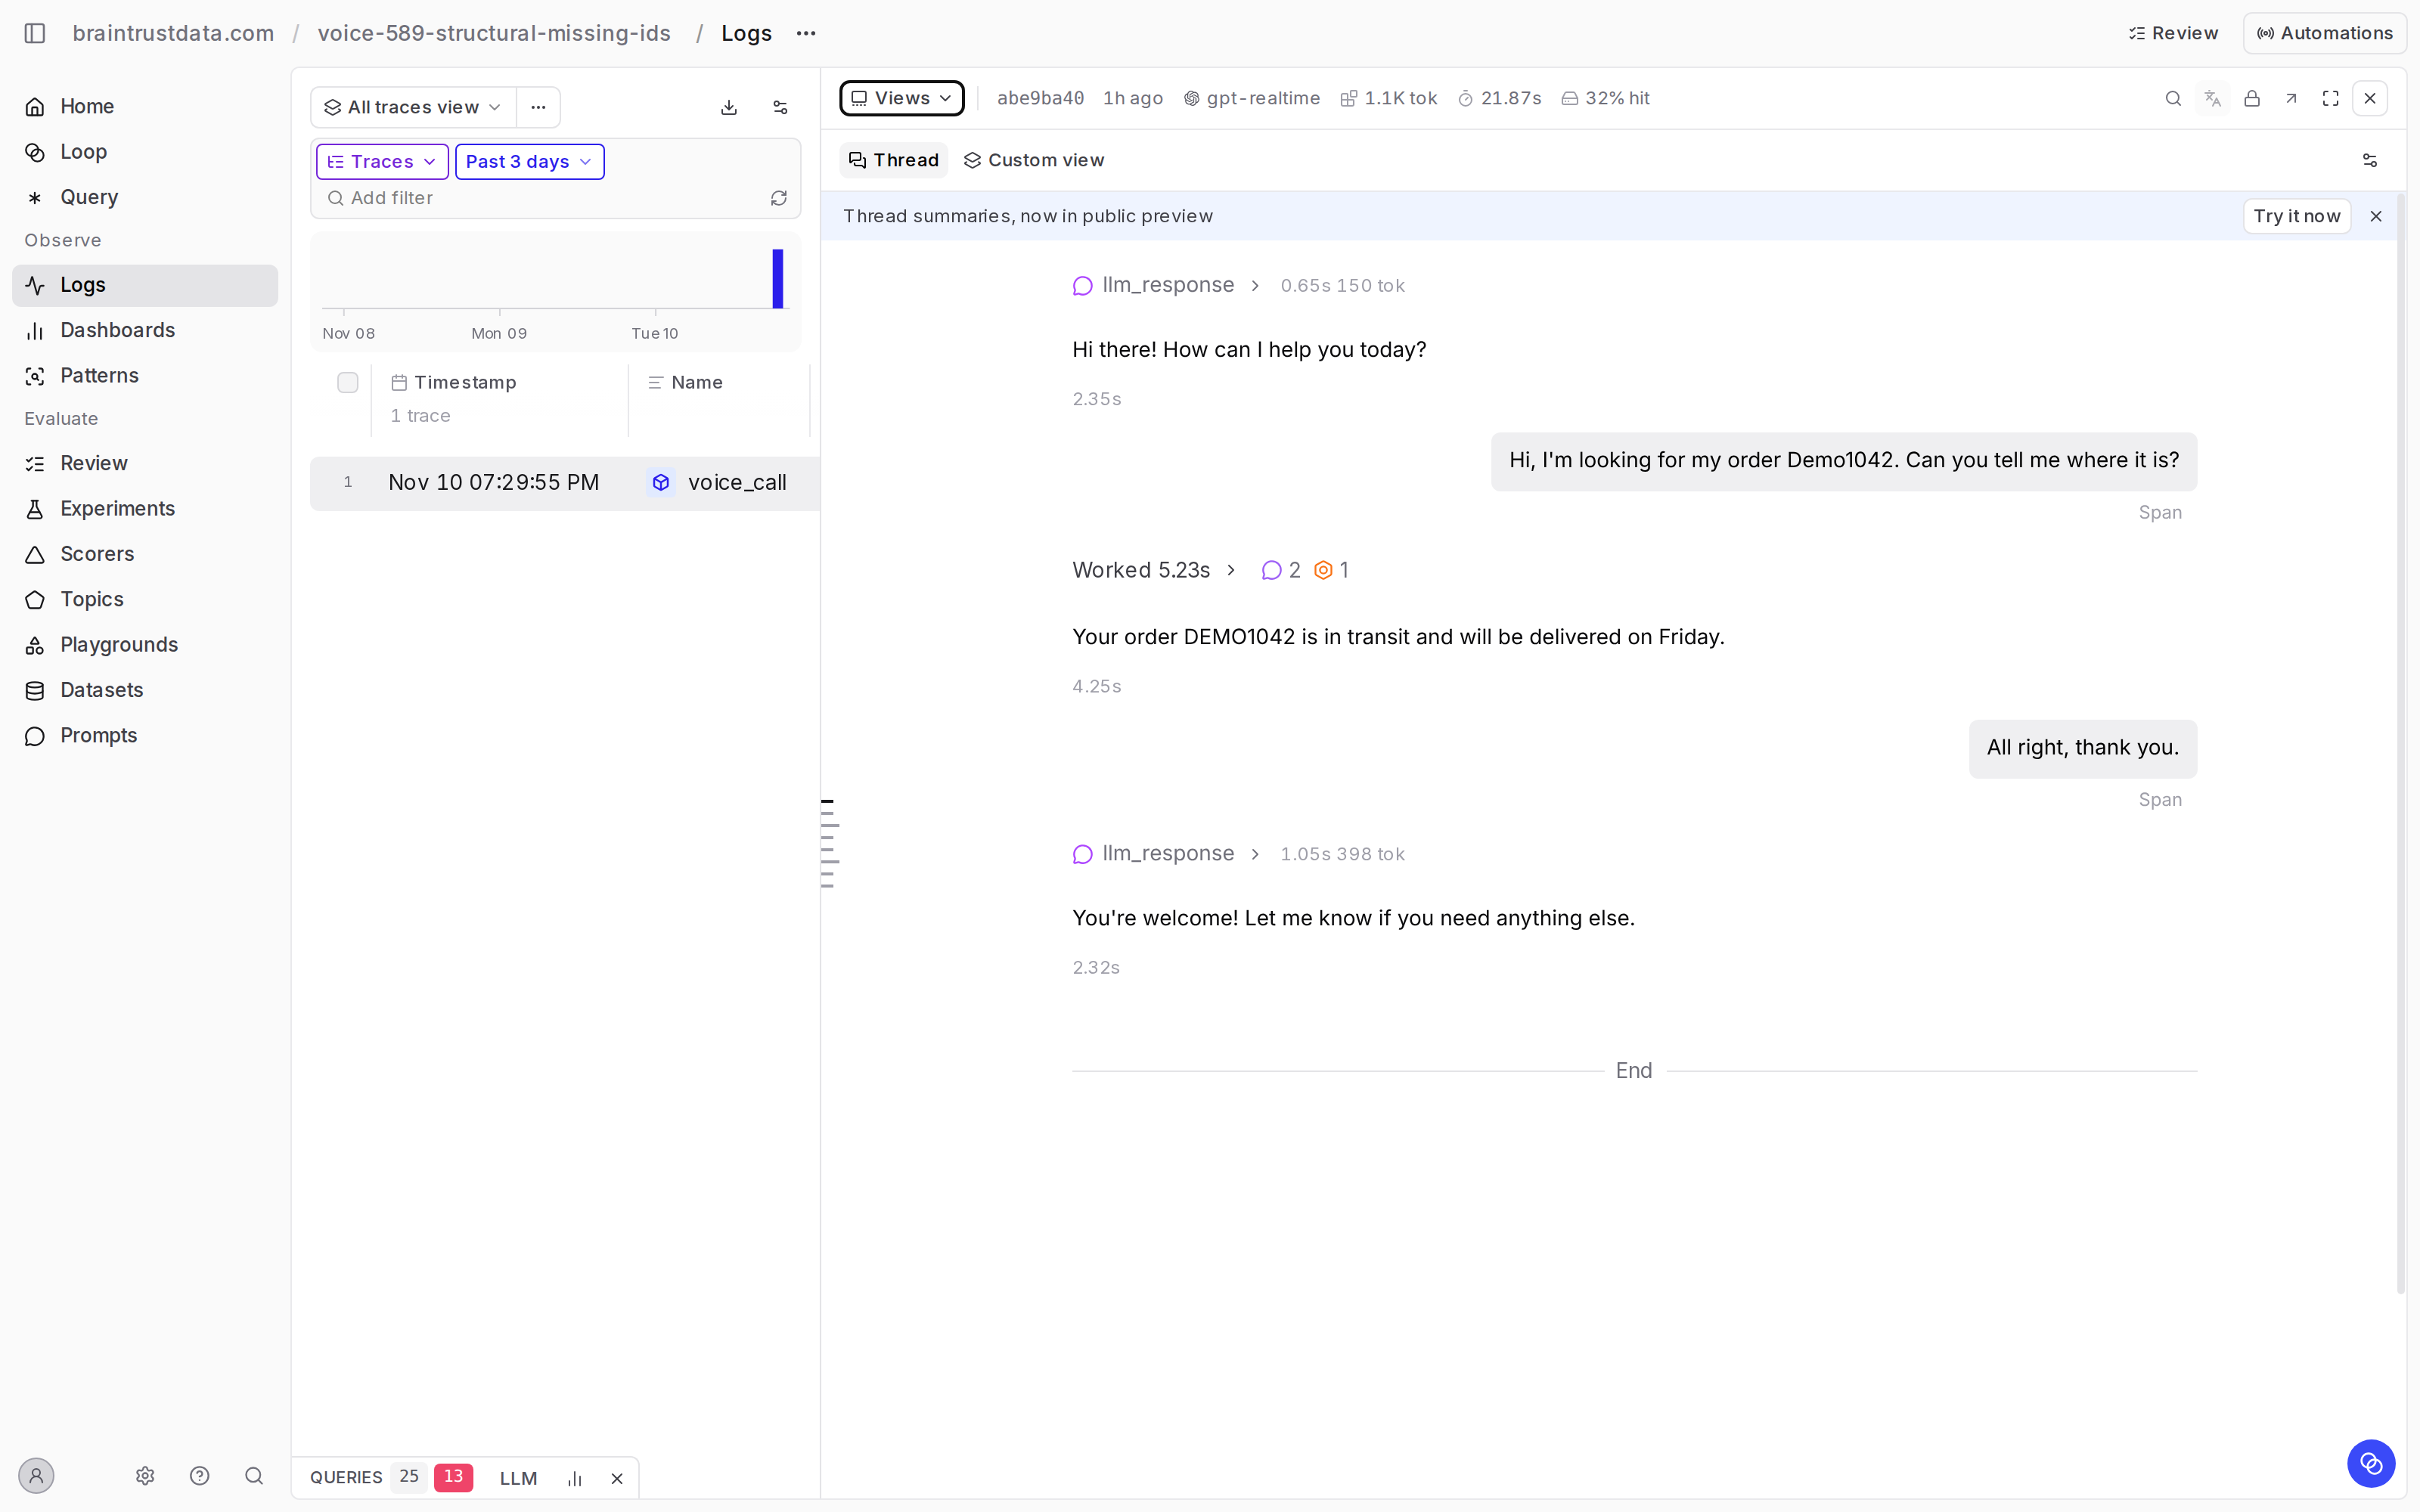 [Open full size](https://api.prod.starfolk.io/api/v1/public/attachments/3GBmzPs4pGuBhxl9Z28wrw/missing-turn-ids-after.png)
This file contains hidden or bidirectional Unicode text that may be interpreted or compiled differently than what appears below. To review, open the file in an editor that reveals hidden Unicode characters.
Learn more about bidirectional Unicode characters
Sign up for free
to join this conversation on GitHub.
Already have an account?
Sign in to comment





Add this suggestion to a batch that can be applied as a single commit.This suggestion is invalid because no changes were made to the code.Suggestions cannot be applied while the pull request is closed.Suggestions cannot be applied while viewing a subset of changes.Only one suggestion per line can be applied in a batch.Add this suggestion to a batch that can be applied as a single commit.Applying suggestions on deleted lines is not supported.You must change the existing code in this line in order to create a valid suggestion.Outdated suggestions cannot be applied.This suggestion has been applied or marked resolved.Suggestions cannot be applied from pending reviews.Suggestions cannot be applied on multi-line comments.Suggestions cannot be applied while the pull request is queued to merge.Suggestion cannot be applied right now. Please check back later.
LiveKit records generated model output in
llm_responseand played speech inagent_speech. Treating both as conversational replies showed the greeting and closing reply twice.Represent voice model calls as existing
llm_analysiswork and keepagent_speechas the response. Generated messages, tool calls, usage, and timing remain inspectable in expandable execution entries. No UI changes are required.Also preserve voice turn roles, structural ownership when
turn.idis absent, and empty user turns. Sessions without recording metadata are accepted. The fixture covers the attached conversation’s 18 voice-session spans, including greeting, tool continuation, and closing speech, with identity metadata removed.Stacked on #589. Implementation reference: Python SDK #1069.
Validation
Screenshots
Same app and viewport; baseline #591 versus the updated Lingua WASM.
Before: generated output and played speech appear as duplicate replies.
Open full size
After: played speech appears once; model generations are expandable execution rows.
Open full size
Expanded work before:
Open full size
Expanded work after: model calls and tool execution remain separate inspectable entries.
Open full size